Axis Robotics Builds the Data Engine for the Next Generation of Physical AI
23 September 2026 | Interaction | By Editor Robotics Business NEWS <editor@rbnpress.com>
Chris, Co-Founder and CEO of Axis Robotics, discusses open-source simulation datasets, scalable robot training, sim-to-real learning, and the data infrastructure needed for general-purpose Physical AI.
As robotics moves toward more capable and general-purpose systems, access to large-scale and diverse training data is becoming increasingly important. In an exclusive conversation with Robotics Business News, Chris Feng, Co-Founder and CEO of Axis Robotics, discusses how the company is building data infrastructure to accelerate robot learning and the development of Physical AI.
Chris explains Axis Robotics’ approach to combining simulation, human-teleoperated demonstrations, automated data validation, domain randomization and real-world robot data to address the challenges of training increasingly capable robotic systems. He also discusses the company’s open-source Axis Sim Dataset V1, its expansion across multiple robotic embodiments, and the role of shared datasets and infrastructure in advancing the robotics industry.
The conversation explores why data diversity, rather than scale alone, could play a critical role in enabling robot foundation models to generalize across objects, environments, tasks and real-world conditions.
What was the strategic thinking behind making Axis Sim Dataset V1 open source, and what impact do you expect this decision to have on the development of Physical AI?
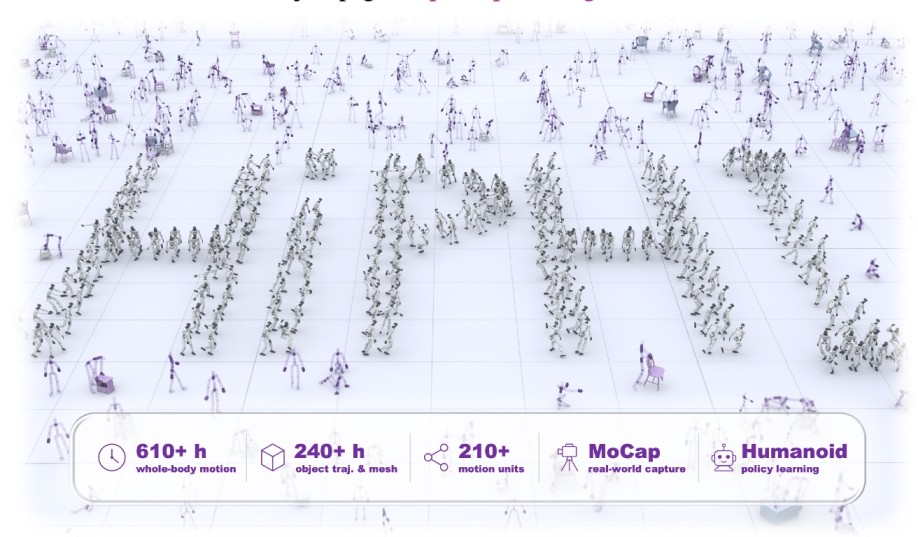
V1 is a public demonstration of the engine that produced it: task generation, browser-based teleoperation, automated processing and augmentation, model training, and a fixed-protocol evaluation. Open-sourcing it lets researchers and companies validate not only the dataset itself, but the tech stack behind it.
The response has been strong: our Franka dataset family has passed 160,000 downloads on Hugging Face, making it the most downloaded open-source simulated Franka manipulation collection, and it is now used by research groups at KAIST, Northwestern, and Tsinghua, and by teams at Yandex and Nota AI. The same pipeline also serves commercial customers across the whole Physical AI stack — embodiment companies like Booster Robotics, model companies like Dexmal and Manycore, and vertical-industry players like Lotus and Geely.
As our slogan puts it: Physical AI should be built by all, not a few. Contributors worldwide generate the data, and its value flows back to both industry and academia.
The dataset includes more than 50,000 human-teleoperated trajectories across 207 manipulation tasks. What were the biggest challenges in collecting, validating and maintaining consistency across such a large and diverse dataset?
The first challenge sits at collection: these trajectories came from a distributed community of retail users operating through a browser — the same contributor network that has since grown past 200,000 people — rather than from trained operators in a lab. Human strategies, skill levels, and motion styles therefore vary widely, and demonstrations contain hesitation and jitter.
Our bet is that this kind of individual noise is tolerable at scale, as long as different people's errors are uncorrelated: the noise averages out while the shared, task-relevant behavior accumulates. Our job is therefore not to filter out every relatively imperfect single trajectory, but to remove what is genuinely invalid while preserving legitimate variation in strategy.
Validation runs as an automated pipeline rather than manual review: structural and physical consistency checks, task-specific success checkers replayed in a backend simulator, removal of failed or corrupted segments and motion artifacts, and a unified trajectory format across all tasks. Valid episodes are then re-rendered with randomized lighting, camera views, materials, and layouts, expanding the same demonstrations into a wider range of controlled variants without changing task semantics.
Simulation is increasingly being used to accelerate robot training. How does Axis Robotics address the challenge of transferring skills learned in simulation to real-world robotic environments?
Simulation alone doesn't close the reality gap, so we close it from both sides. On the simulation side, we pair large-scale domain randomization across objects, layouts, lighting, camera poses, textures, and physical properties, so a policy learns to handle variation instead of overfitting one scene, with task-aligned digital twins that recreate a customer's actual workspace and tasks.
We then adapt that broad simulation-trained model with only a limited set of real-robot demonstrations, and use human-in-the-loop corrections on the failures that surface only in physical deployment, feeding each verified correction back into training.
A concrete example is our commercial partnership with Booster Robotics, a humanoid robot platform company building humanoid hardware, OS, and developer tools, where Axis serves as its first simulation-data partner. We rebuild Booster's workspace as a task-aligned digital twin and have a distributed contributor network collect demonstrations through Axis Suite, diversifying each scene with domain randomization. Accumulated across tasks, more than 42,000 filtered simulation episodes, together with a small curated set of real demonstrations, feed full-parameter continued pretraining of π0.5, producing a Booster-specific foundation model rather than a one-off policy. The clearest sim-to-real evidence came on the physical robot in a low-data setting: with only ten real demonstrations, the policy made no target contact at all across physical rollouts (0 of 20); adding just fifty task-aligned simulation trajectories took that to 17 of 20 — scale and variation from simulation, grounded by just a handful of real trials.
In short, simulation supplies scale and coverage, a small amount of real data supplies alignment, and human correction closes the long tail, with the loop repeating whenever the model meets new real-world conditions.
Why is large-scale and diverse training data becoming such an important competitive advantage in the development of general-purpose robotic intelligence?
General-purpose ultimately means generalization: a robot has to handle objects, scenes, and situations it was never explicitly trained on, and no model can generalize over experiences it has never seen. As hardware rapidly commoditizes and model architectures converge, the bottleneck becomes data.
Unlike LLMs, which inherited the entire internet as training material, robots have no existing corpus of physical experience; every trajectory has to be produced.
Both scale and diversity matter, and diversity is the part most people miss. Repeating tasks the model already masters adds almost nothing; what drives generalization is coverage of the long tail — different objects, materials, layouts, lighting, and the different ways people actually do things. Our own study made this concrete: at the exact same data volume, a comparison dataset (RoboCasa365) reached 57.5% success while AXIS data reached 88.8% — volume alone is not the lever, breadth of coverage is.
This advantage compounds. A larger contributor network produces broader coverage; broader coverage trains stronger models; and those models attract the customers and tasks that draw in still more contributors. A latecomer is not replicating one fixed dataset — they are chasing a flywheel already in motion.
Axis Sim Dataset V1 focuses on manipulation using the Franka Research 3 robotic arm. Are there plans to expand the initiative to other robotic systems or humanoid platforms?
Franka was simply one of the most standardized and widely used manipulation platforms in robotics research, which made it a natural starting point — but never an endpoint. A general-purpose robot foundation model has to be cross-embodiment by definition, so we designed the supply side accordingly: task specifications are decoupled from the robot body, trajectories follow a unified format with embodiment metadata, and the same collection-and-processing pipeline can be re-targeted to new hardware.
Today the engine already spans 13 embodiments, including OpenArm V2, Booster Robotics' T1 humanoid, and Panda Omron. The next-generation dataset is now in development, scaling to 1.2M trajectories across 1,200 tasks, adding more embodiments and stronger results.
By releasing not only the dataset but also training code and benchmarks, what level of collaboration do you hope to encourage among researchers, developers and robotics companies?
By releasing the dataset together with the training code and benchmarks, we wanted to make the claims fully verifiable: researchers and developers can reproduce our results, compare approaches on a common baseline, and build directly on top of the work instead of assembling a new dataset from scratch. It gives the community a shared, fully specified testbed for studying how data quality, diversity, and scale actually affect robot learning.
For robotics companies, we see the open release as a starting point — a common foundation from which to go deeper on embodiment-specific data, custom models, and sim-to-real deployment.
As Physical AI develops, do you believe the robotics industry will increasingly move towards open-source datasets and shared infrastructure, similar to the evolution of the LLMs?
Yes — we think this follows directly from the structure of the problem. LLMs inherited the internet; robots have no equivalent corpus of physical experience, and the long tail of scenes, objects, and human behaviors is far too wide and diverse for any single lab to cover alone.
It is the same conviction behind our slogan, "built by all, not a few," and a foundation built by everyone naturally has to be open and shared rather than locked inside closed pipelines.
But what needs to be shared is not just the dataset itself. Static datasets cannot power general robotic intelligence. The winning solution is a compounding data engine — a system that links a global contributor network with continuous model iteration.
In practice, shared infrastructure means common data formats, reusable processing and validation tooling, and benchmarks with fixed evaluation protocols, so data collected by different teams can actually combine instead of sitting in silos. This is why we released Sim Dataset V1 openly and ship in community formats.
So we expect the LLM pattern to repeat in robotics: open datasets and shared infrastructure at the foundation, with competition moving up to the models and applications built on top.
Looking ahead, what is Axis Robotics' long-term vision for building the data infrastructure needed to train robots that can perform increasingly complex tasks in real-world environments?
Our long-term goal isn't simply to run the world's largest distributed data workforce — that's the engine, not the destination. We're pairing that global contributor network, now over 200,000 people, with our full closed loop, so that data keeps co-evolving with the models it trains instead of arriving as a static shipment. As the model improves, mastered behaviors become redundant and new failure states guide what we collect next — the infrastructure has to move with the model's capability frontier.
Sitting on top of that loop is the real prize: working out the data recipe that actually makes a general-purpose Physical AI model generalize. Pretraining at scale takes a model most of the way; closed-loop refinement grinds through the long tail of real-world complexity that scale alone never covers. Over time, we aim to train strong robot foundation models on that recipe ourselves, rather than only delivering datasets.
General-purpose robots won't come out of a single lab. We want to contribute the infrastructure, the recipe, and eventually the models that help the whole field get there.